Home/ Reports/ 2027 Mid-Market Law Firm AI Benchmark

The 2027 Mid-Market Law Firm AI Benchmark.

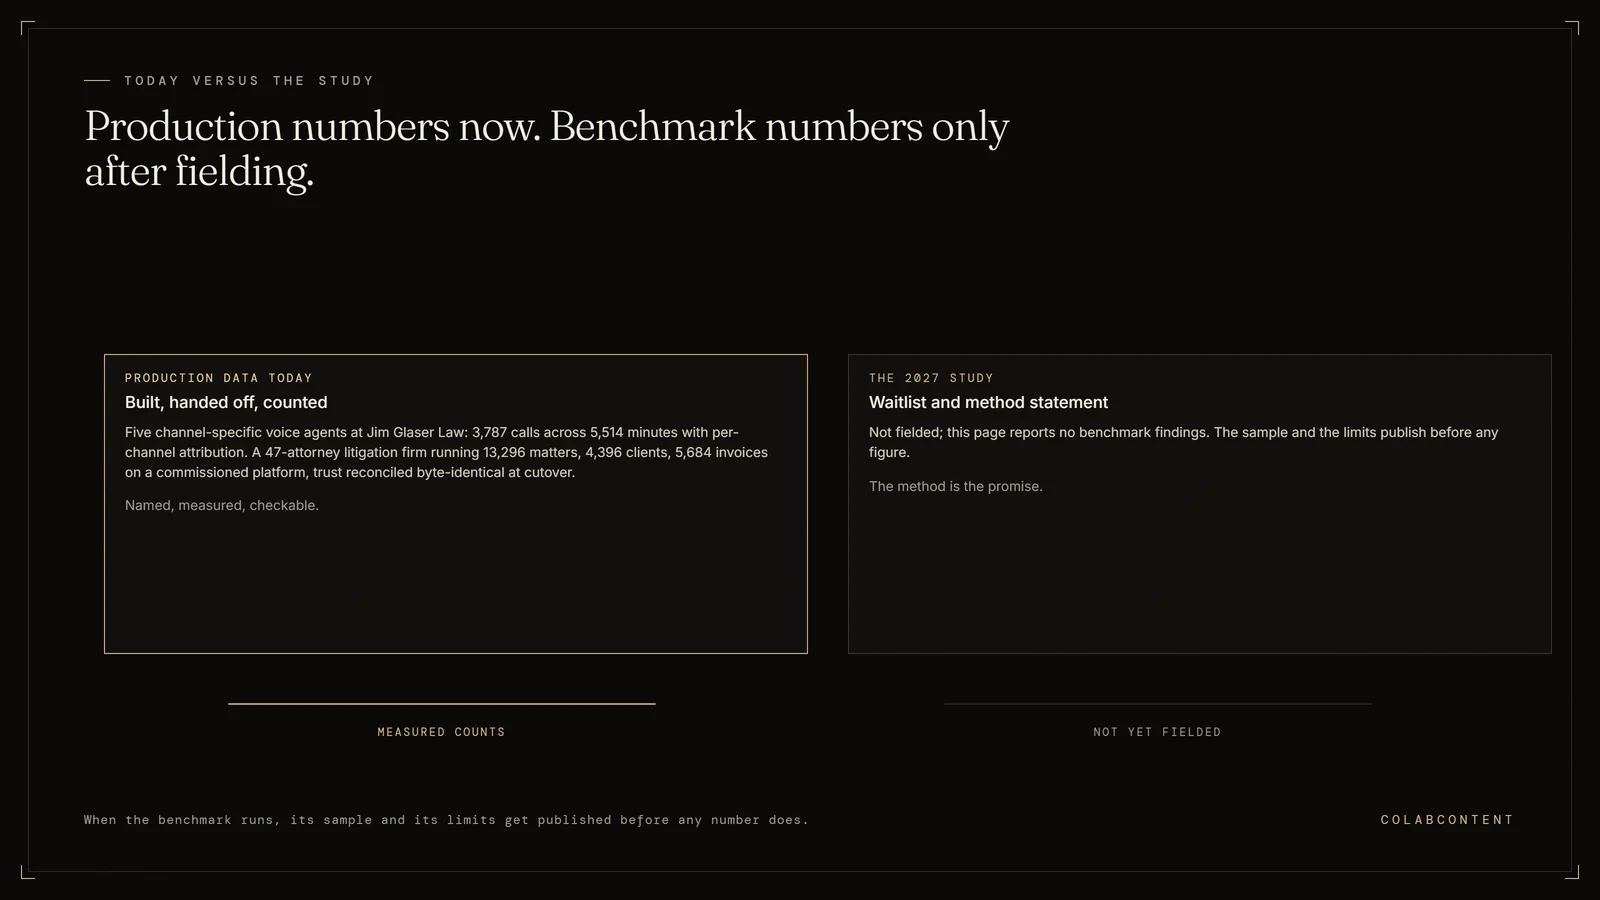
This benchmark has not been fielded yet, so this page reports no benchmark findings. It is the waitlist and the public method statement. What ColabContent can show today is production data from law-firm systems it built and handed off: five channel-specific voice agents at Jim Glaser Law that have handled 3,787 calls across 5,514 minutes, giving per-channel attribution on every answered call, and a commissioned matter, invoice and IOLTA (the client trust account a law firm must keep separate) trust platform at a law firm running 13,296 matters, 4,396 clients and 5,684 invoices, with trust reconciled byte-identical at cutover.

When the benchmark runs, its sample and its limits get published before any number does. This is not the right path for firms with fewer than 20 attorneys (SaaS (software you rent by subscription) economics win at that size), firms whose only AI need is legal research (Harvey and CoCounsel cover that well), or firms without a named workflow constraint worth automating.

The 2027 Mid-Market Law Firm AI Benchmark status: production data today from Jim Glaser Law's five voice agents and a law firm's commissioned matter and trust platform, beside the unfielded study whose sample and limits publish before any number
Real counts on the left; the study stays numberless until fielded.

A planned benchmark of AI adoption and results in mid-market law firms, 20 to 150 attorneys. It has not been fielded. We have not set a sample size, contracted a surveyor, or written the instrument, and we will publish those details with the report rather than promise them here. Target field period Q1 2027; report Q2 2027 if the response supports publishing.

StatusNot yet fielded
Target field periodQ1 2027
Target reportQ2 2027
CostFree

Key Terms

Matter taxonomy: the classification system a firm uses to categorize cases by practice area, client, jurisdiction, and fee arrangement; AI tools that cannot map to the firm's taxonomy create reporting gaps. Conflict-check automation: screening new matters against existing client relationships and adverse parties using pattern matching; a compliance function where manual processes miss edge cases. Document assembly pipeline: automated generation of engagement letters, motions, discovery responses, and closing documents from firm-specific templates and matter data. Data residency: the physical location where client data is stored and processed; a compliance requirement for firms handling matters subject to GDPR, state privacy laws, or client-imposed data handling agreements.

What the report is intended to cover.

Adoption of legal AI tooling (the market products, custom commissions, and internal builds) across firm-size bands, read workflow by workflow: matter intake, contract drafting, document review, deposition summarization, billable-hour reconstruction, knowledge retrieval, client communication.

Product-level detail behind these categories sits in Spellbook legal AI versus a custom build and the iManage AI integration playbook.

Results realization for firms reporting an AI deployment: hours back, dollar impact, recovery of unbilled time. Anything a firm tells us about its own results will be labeled as self-reported. If we run a validation pass on top of that, the report will state how many firms it actually covered.

Stack effects: whether adoption and results vary by primary document management system (iManage, NetDocuments, Clio, SharePoint).

Custom-build versus off-the-shelf: deployment time, results differential, and whether adoption persists at twelve months.

Every one of those is a question we intend to ask, not a finding we already hold.

Methodology preview.

There is no methodology to preview yet, and we would rather say that than invent one. The sample frame, the surveyor, the instrument and the response rate do not exist until the survey is built. When they do, the report will state all four before it states a single finding.

Two commitments we will hold ourselves to. First, the sample size and how firms were sourced get published in the report itself, not summarized on a landing page. Second, if the response is too small or too self-selected to support a quartile analysis, we will publish that fact instead of publishing quartiles.

We expect to open the survey in January 2027. Sign up below to be notified, and to receive your firm's own comparison when there is a cohort to compare against.

Behind the benchmark

Method, limits, and how to use it.

Every figure on this page has a stated source and a stated limit. The notes below explain how the numbers were gathered, where they are estimates rather than measurements, and how to use them in your own decision without treating a benchmark as a quote for your business.

Methodology, and what exists today.

This is a benchmark we intend to run, not one we have run. There is no aggregate data set behind this page, and nothing on it should be read as a benchmark finding. What the practice actually holds today is narrower and more honest: measurements from the production systems it has built and handed off, plus notes from audit calls. Those tell us which dimensions are worth asking about. They are not a survey, they are not a cohort, and we will not dress them up as either.

The dimensions we intend to benchmark are the ones that show up most frequently as the constraint in an audit call: workflow velocity, capacity per senior headcount, response-time distribution, and revenue leakage from operational friction. Those are the dimensions an operator can act on with a commissioned AI build, which is why they are worth measuring at all.

How the benchmark is designed to be read.

The design splits operators in the vertical into four quartiles on each dimension, on the expectation that the top and bottom quartiles carry the signal and the middle two sit close together. That is the design assumption, and the survey is what tests it. The benchmark is meant to tell an operator where their workflow stands relative to other operators in the band, not relative to a theoretical optimum.

The comparison we expect to be most actionable is top quartile minus middle quartile on the dimension that is the operator's known constraint. Expressed in dollars or hours, that delta is the upside a commissioned AI build would be asked to close. We do not have that delta yet for this vertical, and we will not estimate one before the data exists.

What the benchmark does not say.

Start with the largest limit: it will not say anything at all until it is fielded. Once it is, it still will not say that every operator in the vertical should be top quartile on every dimension. Some dimensions are not worth optimizing for a specific firm's business model. A contingency-fee practice cannot and should not optimize for the same billable-hour realization number as an hourly commercial litigation shop. The benchmark is a yardstick, not a prescription.

It also will not say that AI is the right intervention for closing any specific gap. Some gaps close better with process redesign, some with staffing changes, some with stack changes. We will tell the operator on an audit call when the right answer is not AI.

How the benchmark feeds into an audit call.

Once the benchmark exists, operators will bring it to an audit call and we will walk through which dimensions they are top quartile on, which they are bottom quartile on, and which of the bottom-quartile dimensions is worth commissioning a build to close. Until then the call runs the way it runs today, off the operator's own numbers rather than a cohort score. The audit call ends with the constraint written down in a sentence.

Where to look next.

The reports hub indexes what the practice publishes by vertical, including which reports are planned rather than shipped. The best-by-vertical guides cover the AI consultants and platforms relevant to each vertical. The resources section holds the decision frameworks this benchmark is meant to feed into.

Extended questions

The questions buyers ask after the first one.

These are the questions that come up once the first one, whether to build at all, has been answered. Each answer below is the one we give on the call that ends the $499 AI-Ready Audit, written down here so it can be checked against your own report before anything is commissioned.

How to evaluate references the consulting house presents.

Three questions per reference. First, what was the named constraint the commission addressed at this operator. Second, what was the measured result after handoff, in dollars or hours. Third, does the reference operator still run the system. Vague references on any of those three are flags, and so is a house that offers written case studies but no phone number. ColabContent introduces prospects to the operators who have agreed to take those calls; Jim Glaser Law is one of them, and Jimmy takes reference calls directly. A fifteen-minute call to an operator who actually runs the system is the most honest signal a prospect can get.

Vertical context

How to read this benchmark for mid-market law firms.

This section covers the structural constraint mid-market law firms face around partner time and billable-hour leakage, how to read the dimensions that matter most for this vertical, what the benchmark deliberately does not claim about any single firm, and how to bring these numbers into an actual audit call.

The vertical-specific constraint.

Mid-market law firms face a recurring constraint that is structural rather than tactical: partner time leaks out of the billable-hour engine through timesheet reconstruction, matter-routing friction, and document automation gaps that off-the-shelf legal AI products do not address at the firm-specific calibration level.

In the audit calls we have run with Managing Partners and Firm Administrators in the 20 to 150 attorney band, the leading entry is usually unbilled partner time or matter-routing accuracy. That is an observation from our own calls, not a survey result, and part of what the benchmark is meant to test is whether it holds across the vertical.

Reading the dimensions that matter most for this vertical.

The benchmark is designed to score mid-market law firms on a set of dimensions, and we expect two to carry the most weight. The first is billable-hour realization rate, because it lands directly on the P&L. The second is intake-to-matter routing time, because a matter that routes slowly is a matter that can be lost before it is opened. How wide the spread actually is between quartiles on either dimension is exactly what we do not know yet, and it is the reason to field the survey rather than assert a figure.

What we can describe without a benchmark is the law-firm work already shipped. At Jim Glaser Law, five channel-specific voice agents (PPC, Organic, TV, Meta and LSA) have handled 3,787 calls across 5,514 minutes, which gives the firm per-channel attribution on every answered call rather than a single undifferentiated intake line. At a law firm, the matter, invoice and IOLTA trust system runs on a commissioned platform carrying 13,296 matters, 4,396 clients and 5,684 invoices, with trust reconciled byte-identical at cutover. Neither engagement started from a quartile score. Each started from a named workflow, which is the same place a commission starts today.

What the benchmark does not say about mid-market law firms.

Because it has not been fielded, it currently says nothing at all, and any figure attributed to it would be a figure that does not exist. Once it ships, it still will not say that every mid-market law firm should be top quartile on every dimension. Some dimensions are not worth optimizing for a specific firm's business model, so the benchmark is a yardstick rather than a prescription. It also will not say that AI is the right intervention for closing any specific gap. Some gaps close better with process redesign, some with staffing changes, some with stack changes. We tell the operator on an audit call when the right answer is not AI.

How to bring this benchmark to an audit call.

When the benchmark ships, operators will bring it to the audit call and we will walk through where the firm sits on each dimension. Bottom-quartile dimensions become the candidates for a commissioned build. Top-quartile dimensions become leverage points to defend rather than improve. Until then the call works from the firm's own measurements, which is how every commission to date has actually started. The conversation ends with the leading constraint written down in a single sentence and an honest assessment of whether a custom AI commission is the right buying motion. Many calls end with us recommending an alternative (off-the-shelf product, internal hire, no AI right now) rather than a commission; the never-overbook rule means we only take engagements where the commission is the right fit.

Run your firm's diagnostic now.

The 12-question Billable-Hour Recovery Diagnostic runs free and on demand, producing your firm's annual leakage figure on screen in minutes. It uses the same dimensions this benchmark tracks, scaled to your own numbers, so you can see where partner time is leaking before booking a call.

The 12-question Billable-Hour Recovery Diagnostic. Free, on demand, your firm's annual leakage figure on screen.

About this report

ColabContent reports analyze AI implementation patterns from the work we actually ship. This particular report has not been produced yet; this page describes what it is intended to measure and holds the notification list. Pages are reviewed quarterly and corrected when something on them stops being accurate.

Methodology: where a number appears anywhere on this site, it comes from a production system we built, and it is either attributed to a named client with that client's agreement or described in anonymized form with the vertical named. Figures a client reports about its own business are labeled as self-reported. We do not publish composite, illustrative, or representative figures, and we do not present a planned study as a completed one.

About ColabContent: a private AI consulting house in Boston, Massachusetts. ColabContent LLC was founded in 2020 as a content practice; the AI practice has been shipping since 2024. Across client systems, more than 6,000 live calls have been handled to date. We commission custom AI for growth-stage businesses, principal-run, never overbooked. To inquire about a commission or sponsor a research engagement, book a $499 AI-Ready Audit on the contact page.

Citation: this page describes a planned report, not a published one, and should be cited as such by title and URL with attribution to ColabContent. Once the report ships, it will carry its own citable figures.

Next step

Start with the $499 audit. Bring the firm's current matter-management workflow, the document management system, and the three highest-volume document types. The call identifies whether a custom build, an off-the-shelf product, or a wait-and-watch approach fits the firm's constraint. The call is part of the audit; no obligation after it.

Related reading: Resources, Framework for AI Buying Decisions.

Related reading: Law Firms Billable Hour Diagnostic (Free, 2 Min).