Home/ Reports/ 2027 Mid-Market P&C Agency AI Benchmark

The 2027 Mid-Market P&C Agency AI Benchmark.

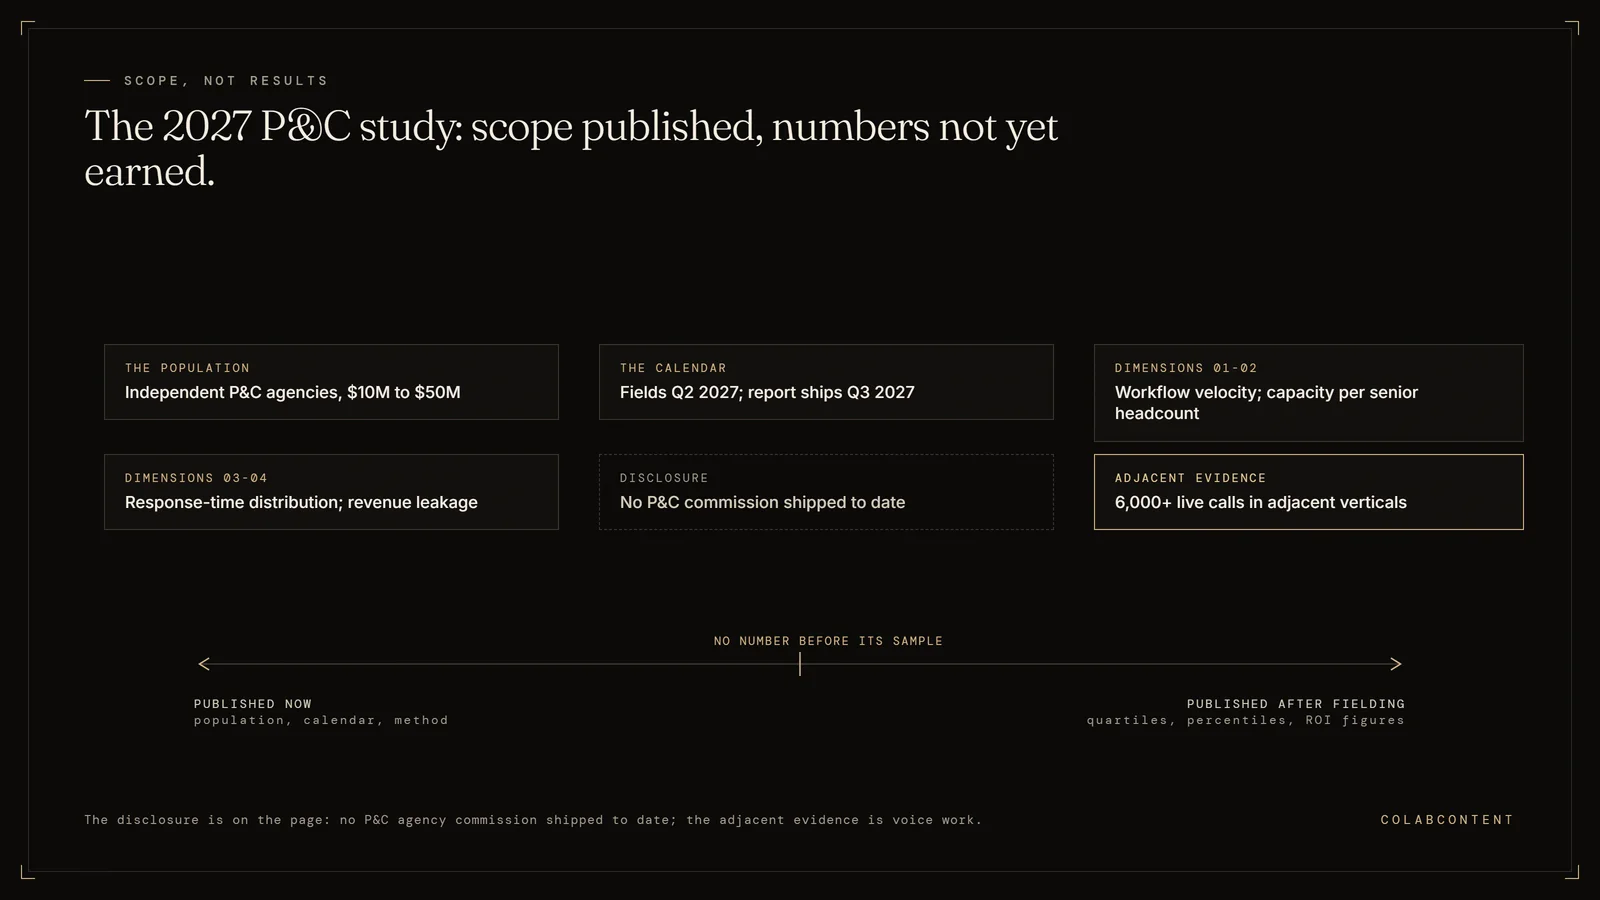
This benchmark has not been fielded yet. The field period opens in Q2 2027 and the report ships in Q3 2027, so there are no quartiles, percentiles, or ROI figures for this vertical on this page. What is published here is the scope: the dimensions the study will measure (workflow velocity, capacity per senior headcount, response-time distribution, and revenue leakage from operational friction), the population it will sample (independent P&C, property and casualty, agencies in the $10M to $50M band), and the method it will use. ColabContent has not shipped a commission for a P&C agency to date.

The production work behind the response-velocity dimension is real and lives in adjacent verticals: more than 6,000 live calls handled across client deployments, including 3,787 AI-handled calls and 5,514 minutes for Jim Glaser Law across five channel-specific voice agents. This is not the right path for agencies with fewer than 15 producers (SaaS economics win), agencies whose only need is quoting (rater tools cover that), or agencies without a named submission or renewal constraint worth automating.

The decision framework. Three questions decide it: (1) does the agency's submission workflow fit what existing InsurTech (EZLynx, Zywave, Indio) already automates, or does it carry specialty lines; (2) do carrier contracts allow a SaaS (software you rent by subscription) vendor to process policy data, or must the agency control its own infrastructure; (3) over 24 months, does a per-user subscription cost less than a one-time build. Any "no" makes the build worth sizing. Key definitions. Submission-to-bind ratio: the percentage of submissions to carriers that result in bound policies. Carrier appetite matching: routing submissions to carriers whose underwriting guidelines align with the insured profile. The next step. The $499 AI-Ready Audit sizes the gap in dollars and weeks. If the answer is a product, we say so.

The 2027 Mid-Market P&C Agency AI Benchmark scope: independent agencies at $10M to $50M commission revenue, fielding in Q2 2027 and shipping Q3 2027, scoring workflow velocity, senior capacity, response time, and leakage, with the disclosure that no P&C commission has shipped
Population, calendar, dimensions, and the disclosure, before any data.

A planned benchmark of AI adoption and ROI in mid-market independent P&C agencies ($10M-$50M). To be segmented by AMS360 vs Applied Epic vs EZLynx, by commercial-vs-personal mix, and by agency size. Field period Q2 2027, so no findings exist yet. This page is the scope and the method, published in advance.

PanelIndependent P&C agencies · $10M-$50M
Field periodQ2 2027
Report shipsQ3 2027
CostFree

Key Terms

Handoff documentation: the package of code, prompts, models, datasets, and runbook (the written operating instructions) that transfers a commissioned system to the operator. Prototype validation: a working demonstration on the operator's real data, delivered before payment; surfaces whether the constraint is actually addressable. Integration surface: the set of APIs, data formats, and authentication mechanisms connecting an AI system to existing tools; the strongest predictor of implementation timeline. Vendor lock-in: the cost and difficulty of switching providers once data, workflows, and training are invested; code ownership eliminates it.

What the report will cover.

Adoption rates of insurance AI tools across three agency size bands. Workflow-by-workflow: COI (certificate of insurance) generation, submission packaging, renewal management, producer onboarding, claims, customer communication.

For the automation layer specifically, see Quandri renewal automation versus a custom build and the EZLynx API automation playbook.

ROI (return on investment) realization: hours-back, retention impact, win-rate uplift on submissions, commission revenue impact.

Stack effects: how adoption and ROI vary across AMS360, Applied Epic, EZLynx, HawkSoft. Custom commission vs off-the-shelf split.

Behind the benchmark

Method, limits, and how to use it.

Every figure on this page has a stated source and a stated limit. The notes below explain how the numbers were gathered, where they are estimates rather than measurements, and how to use them in your own decision without treating a benchmark as a quote for your business.

Methodology behind the benchmark.

The honest starting point: this benchmark has not been run. The field period opens in Q2 2027 and the report ships in Q3 2027, so there is no data set to describe yet, only a method we are committing to in advance so a reader can judge it before the numbers exist.

When it runs, the source data will come from two places. First, a structured survey of agencies in the band who opt into the panel, aggregated with identifying details removed. Second, post-handoff measurements from ColabContent commissions where the operator has consented to anonymized benchmarking. It will not be a roll-up (a group of businesses bought and combined by one owner) of public earnings filings, not a re-publication of a third-party industry report, and not an extrapolation from a single named engagement. Where a segment's sample is too thin to report, we will say so and leave the cell empty rather than fill it with an estimate.

The dimensions we will benchmark are the ones that come up most frequently as the constraint in an audit call: workflow velocity, capacity-per-senior-headcount, response-time distribution, and revenue-leakage from operational friction. We chose these dimensions because they are the ones an operator can act on with a commissioned AI build.

How to read your operator's position in the benchmark.

When the report ships, it will split responding agencies into quartiles on each dimension, so an operator can see where their workflow stands relative to other agencies in the band rather than relative to a theoretical optimum. Until the field period closes there is nothing to read: any P&C quartile, percentile, or peer average attributed to this benchmark before Q3 2027 did not come from us.

The comparison we expect to be most useful is the operator's own position against the top quartile on the dimension that is their known constraint. That delta, expressed in dollars or hours, is the upside a commissioned AI build would be asked to close. The benchmark cannot produce that figure for anyone yet. An audit call can produce a rough version of it today, using the operator's own numbers rather than a peer panel.

What the benchmark does not say.

It will not say that every agency should be in the top quartile on every dimension. Some dimensions are not worth optimizing for a specific operator's business model. An agency whose book is mostly complex commercial lines cannot and should not chase the same quote-turnaround number as a personal-lines shop. The benchmark is a yardstick, not a prescription.

It will also not say that AI is the right intervention for closing any specific gap. Some gaps close better with process redesign, some with staffing changes, some with stack changes. We will tell the operator on an audit call when the right answer is not AI.

And it will not carry a result we did not measure. If the Q2 2027 field period does not reach a usable sample, this page will say the study was not completed rather than publish thin numbers dressed as findings.

How the benchmark feeds into an audit call.

Once the report ships, operators will be able to bring it to an audit call and walk through which dimensions they sit high on, which they sit low on, and which of the low ones is worth commissioning a custom AI build to close. Until then the call runs off the operator's own measurements instead of a peer panel, which is slower to contextualize but no less concrete. Either way the audit call ends with the constraint written down in a sentence.

Where to look next.

The reports hub indexes the benchmarks across the five verticals the practice covers, and marks which are fielded and which are still scoped. The best-by-vertical guides rank the AI consultants and platforms relevant to each vertical. The resources section holds the decision frameworks that the benchmark is meant to feed into.
Extended questions

The questions buyers ask after the first one.

These are the questions that come up once the first one, whether to build at all, has been answered. Each answer below is the one we give on the call that ends the $499 AI-Ready Audit, written down here so it can be checked against your own report before anything is commissioned.

How to evaluate references the consulting house presents.

Three questions per reference. First, what was the named constraint the commission addressed at this operator. Second, what was the measured result twelve months post-handoff, in dollars or hours. Third, does the reference operator still run the system. Vague references on any of those three are flags. ColabContent will arrange a reference call with Jim Glaser Law, the named operator behind the voice-agent work described further down this page; a fifteen-minute call to the operator is the most honest signal a prospect can get.

Vertical context

How to read this benchmark for regional P&C insurance agencies.

This section covers the velocity constraint specific to regional P&C agencies, how to read the benchmark's dimensions in that light, what the report deliberately will not claim about any single agency, and how to bring the finished numbers into an actual audit call once the field period closes and the report ships.

The vertical-specific constraint.

Regional P&C agencies operate under a velocity constraint that stays invisible until someone measures it. Response speed on a certificate request or a submission is the thing a commercial client actually experiences, and most agencies have never timed it. The spread between the fastest agencies and the middle of the market has not been measured here, and measuring it is what the 2027 field period is for.

Our working hypothesis, drawn from what agency principals and owners raise on audit calls rather than from a study, is that the leading constraint in the $10M to $50M commission revenue band is COI (certificate of insurance) turnaround velocity and submission processing depth. The field period will test that hypothesis. It is not a finding, and we will publish it as wrong if the panel says so.

Reading the dimensions that matter most for this vertical.

The benchmark will score agencies on a set of dimensions, and we expect two of them to carry disproportionate weight. The first is COI median turnaround time. The second is submission queue depth at quarter close. We are not publishing a spread for either one, because we have not measured either one across the vertical. Both are worth noting for a different reason: an agency can pull both numbers out of its own management system this quarter, without waiting for the report or for us.

Being plain about the gap in our own record: ColabContent has not shipped a commission for a P&C agency yet, and borrowing a result from another vertical to fill that space would make this page worthless. What we have shipped is the response-velocity layer this benchmark is largely about. More than 6,000 live calls have been handled in production across client deployments. For Jim Glaser Law that is 3,787 AI-handled calls and 5,514 minutes across five channel-specific voice agents (PPC, Organic, TV, Meta, LSA), which gives the firm per-channel attribution on every answered call. A multi-location home services operator runs the same pattern at 1,486 AI-handled calls and 2,203 minutes. Jim Glaser Law will take a reference call from a prospect who wants to hear it from the operator instead of from us.

The build logic is unchanged by the missing vertical case study. The commission addresses a named dimension. The dimension translates into a workflow. The workflow translates into a build.

What the benchmark does not say about regional P&C insurance agencies.

Today it says nothing at all, because it has not been fielded. When it ships it will not say that every regional P&C agency should be in the top quartile on every dimension. Some dimensions are not worth optimizing for a specific operator's business model. The benchmark is a yardstick, not a prescription. It will also not say that AI is the right intervention for closing any specific gap. Some gaps close better with process redesign, some with staffing changes, some with stack changes. We tell the operator on an audit call when the right answer is not AI.

How to bring this benchmark to an audit call.

From Q3 2027, operators will bring the benchmark to the audit call and we will walk through where they sit on each dimension. The dimensions where the operator lands low become the candidates for a commissioned build. The dimensions where the operator already leads become the leverage points to defend rather than improve. Before then the same call runs on the agency's own COI and submission timings, which any agency can pull ahead of the call. The conversation ends with the leading constraint written down in a single sentence and an honest assessment of whether a custom AI commission is the right buying motion. A commission, where it is the right fit, is a single fixed fee from $10,000. Many calls end with us recommending an alternative (off-the-shelf product, internal hire, no AI right now) rather than a commission; the never-overbook rule means we only take engagements where the commission is the right fit.

A note on the data window: there is no data window yet. Collection opens with the Q2 2027 field period and the report ships in Q3 2027. When it ships, this note will name the exact operating quarters the measurements cover and the date the window closed, so a reader can weight recency for themselves. Until that happens, nothing on this page should be read as a measured result for the P&C vertical.

A further note on application: once the panel data exists, operators scoping a custom AI commission should look hardest at the dimensions where their position trails the top quartile by the largest absolute margin, since those carry the most measurable upside. In the meantime the same logic works without peer data. Measure the two numbers named above inside your own management system, and bring the worse of the two to the audit call. The call surfaces which one is the actual leading constraint.

Run your agency's benchmark now.

The COI Bottleneck Benchmark. 10 inputs, scored on the operational dimensions this study will test. It scores against the thresholds we use on audit calls today; peer-panel percentiles arrive only when the report ships in Q3 2027.

About this report

ColabContent reports analyze AI implementation patterns from our commission work and from surveys we field with operators in a given vertical. Some reports, including this one, are announced before their field period opens. Those pages publish scope and method only and carry no results. Every report page states its field period and ship date near the top so a reader can tell in one glance which kind they are looking at.

Methodology: where a report carries measurements, they come from active commissions in which the client consented to anonymized benchmarking, plus survey responses from operators who opted into the panel, supplemented by published industry sources with citation. Sample sizes are stated per section. Outliers are reviewed manually and excluded with explicit reasoning where they would distort an aggregate. Where a segment's sample is too thin to report, the cell is left empty rather than estimated.

About ColabContent: ColabContent LLC, a private AI consulting house in Boston, Massachusetts, founded in 2020 and shipping AI commissions since 2024. Work to date includes more than 6,000 live calls handled in production across client deployments and a full law-firm platform migration covering matters, invoicing and IOLTA (the client trust account a law firm must keep separate) trust accounting. Principal-run builds, never overbooked. To inquire about a custom commission or to join the 2027 P&C panel, book a $499 AI-Ready Audit on the contact page.

Citation: cite this report by its title and URL with attribution to ColabContent. We track citations and appreciate links back from research, journalism, and operator content.

Next step

Start with the $499 audit. Bring the agency's current AMS (agency management system), the submission-to-bind ratio, and the renewal workflow that costs the most staff time. The call identifies whether a custom build, an InsurTech (insurance-specific software) product, or process redesign closes the gap. The call is part of the audit; no obligation after it.

Related reading: EZLynx API: The Five APIs, Access Rules, and Integrations.

Related reading: Resources, Framework for AI Buying Decisions.

Related reading: Insurance Agencies Agency Velocity Benchmark (Free, 2 Min).

Related reading: The Mid-Market AI Benchmark Series (Planned).